 Legal
AI for Immigration Forms: Docketwise vs INSZoom vs Custom
Why immigration work is unusually well-suited to agents
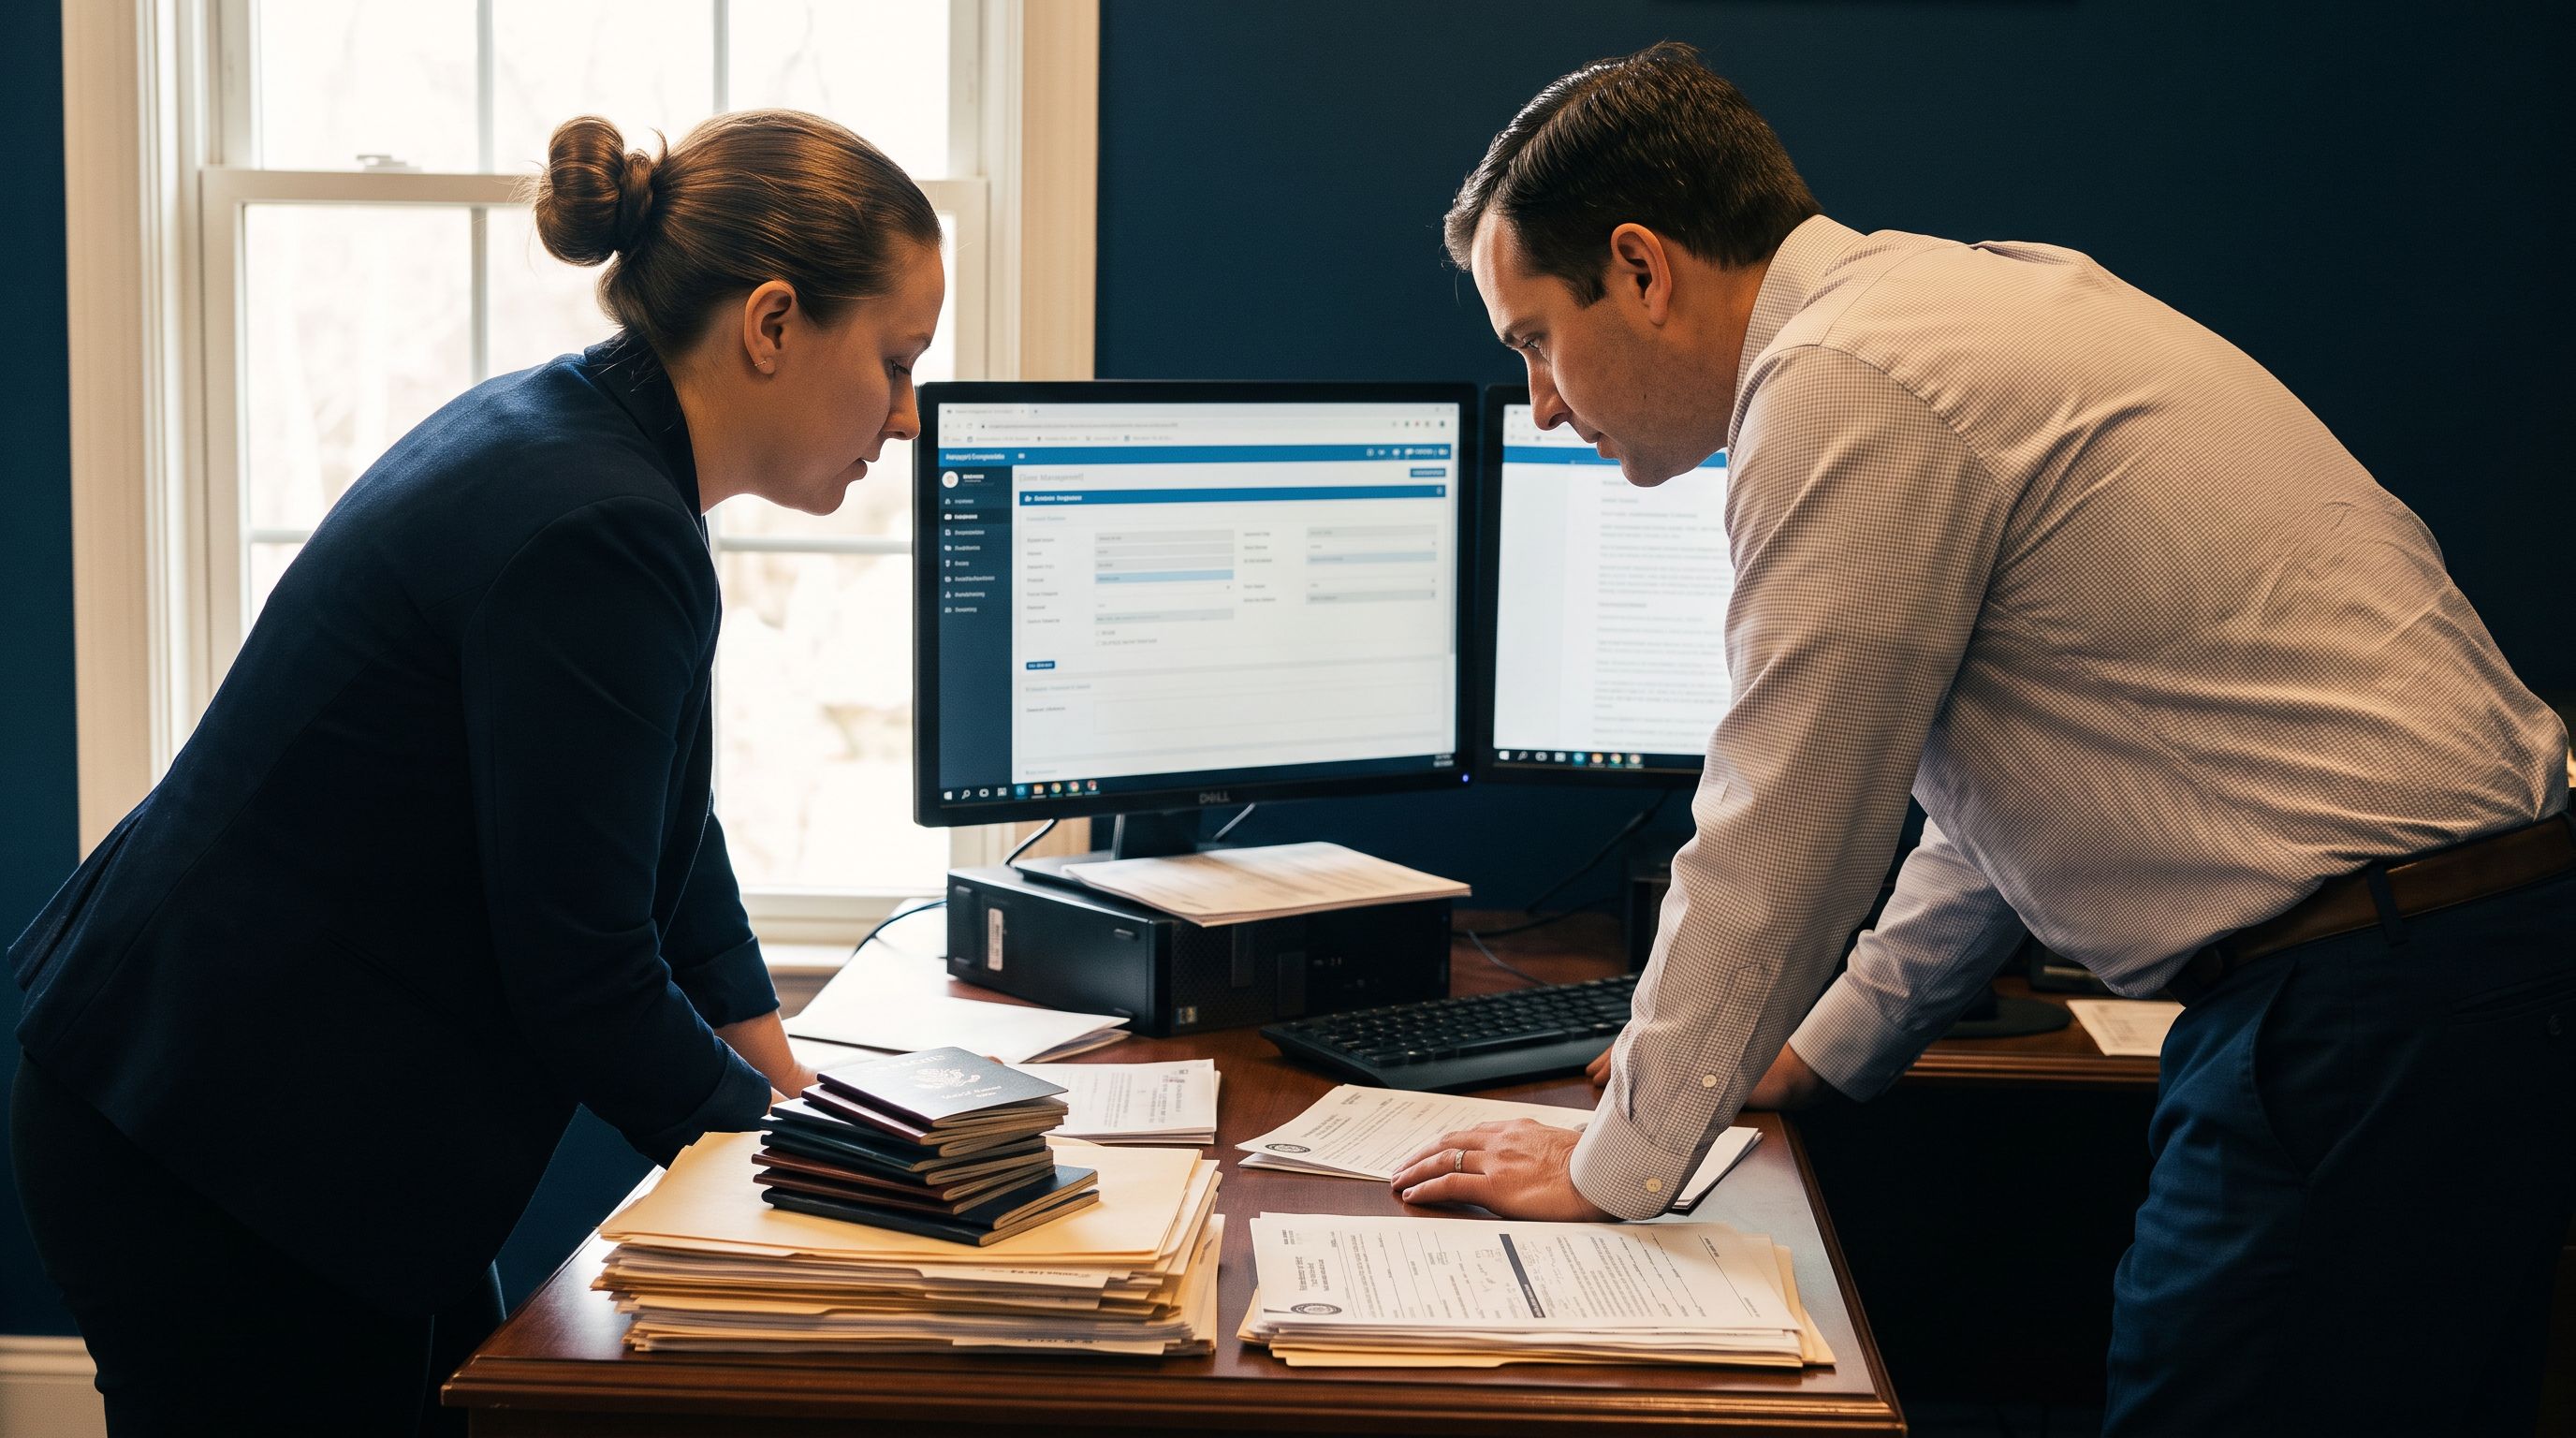
Most legal AI pitches are vague. Immigration form prep is not. A family-based package, an H-1B extension, a naturalization application — each is a defined set of official forms with defined fields, fed by a defined set of source documents: passports, I-94 records, birth and marriage certificates, prior approval notices, pay stubs, tax transcripts.
That structure is exactly what an AI agent handles well. The work is high-volume, rule-bound, and verifiable. Unlike brief writing, you can check every output against a source document in seconds. Unlike legal research, there is a right answer sitting in a PDF.
It is also exactly where firms bleed. Typing an address from a lease into three different forms is not legal judgment. It is data movement with malpractice consequences.
Mechanical work vs. judgment work in a package
Every immigration package splits into two kinds of work, and they deserve very different treatment. Roughly speaking — this is a working heuristic, not a measured finding — the split looks like this:
- Mechanical work: extracting biographic data, transcribing document numbers, populating repeated fields across forms, assembling exhibit indexes, tracking which supporting documents are still missing.
- Judgment work: eligibility strategy, inadmissibility issues, disclosure decisions, how to characterize employment duties, whether to file at all.
AI should be aimed squarely at the first category and kept on a short leash near the second. A firm that automates the mechanical side and reinvests that time into more consultations and more matters is running the same play as any leveraged practice — more billable or flat-fee matters per attorney, without more headcount. The honest formula is throughput × average fee × realization, minus cost. Plug in your own numbers; AI only moves the throughput and cost terms.
Three ways to put AI on immigration forms
Option 1 — Immigration-specific case management with built-in AI. Docketwise and INSZoom are built around immigration workflows: smart forms, client questionnaires, form libraries, deadline tracking. Before you assume anything about their AI capabilities, check each vendor’s current feature and pricing pages for what is actually included in the tier you’d buy — this moves quarterly across the whole legal software market. Their structural advantage is that they maintain the forms, the field mappings, and the filing plumbing, and you don’t.
Option 2 — General AI assistants. Claude, ChatGPT, Copilot, or legal-specific tools like CoCounsel are strong at reading a stack of scanned documents and producing a clean summary or draft. Their weakness is that they don’t natively know your matter, your client record, or where the data has to land. Without a connection to your systems, a human copies the output across — which is where errors creep back in.
Option 3 — A custom agent connected through MCP. MCP (Model Context Protocol) is an open standard for giving an AI assistant governed access to your data and tools. You can connect an assistant to your document store and case management system so it can read the matter file and write back — the same pattern described in building a custom MCP server over your firm’s matter data. Add a skill — a packaged, reusable instruction set — that teaches the assistant your firm’s exact method for preparing a given package, and you get the same output shape every time.
Strengths: the vendor maintains form editions and field mappings; filing and deadline workflow already exist; lower setup burden; support when a form changes.
Limits: you get the vendor’s roadmap, not yours; AI features vary by tier and change often; document intake from messy client uploads is often still manual.
Best for: firms whose bottleneck is forms and deadlines, not document chaos.
Strengths: reads unstructured client uploads (phone photos, WhatsApp exports, prior counsel files), applies your firm’s checklist, writes structured data into whatever system you already use, and produces an exception report.
Limits: you own maintenance forever. Someone on staff must monitor form editions, run regression tests on your prompts and skills when you change them, and re-validate output quality after every model update — that is recurring staff time on the payroll every month, not a one-off build cost. It also needs real governance, and it isn’t worth it below a certain volume.
Best for: firms with high repeat volume in a handful of case types and a document-intake bottleneck.
The right build is usually not “replace the platform.” It’s “put an agent in front of the platform and let the platform stay the system of record.”
What the agent actually does, step by step
-
Collect and classify
The client uploads twelve files with names like IMG_4471.jpg. The agent classifies each one — passport biographic page, I-94, marriage certificate, prior receipt notice — and renames and files them to the matter folder in your document system. -
Extract to a structured record
It pulls names, dates, document numbers, addresses and employment history into a structured field set, keeping a pointer back to the source page for every value. Provenance is non-negotiable: every field should be clickable back to the document it came from. -
Cross-check for conflicts
Name spellings that differ between the passport and the birth certificate. A date of entry that doesn’t match the I-94. Address history with a six-month gap. The agent surfaces these as flags — it does not silently pick a winner. -
Populate and draft
It writes the data into your case management system’s fields or generates the draft package, plus a cover checklist of what is still missing from the client. -
Human review before anything leaves
A paralegal reviews the exception list and spot-checks fields against sources; the attorney reviews eligibility and disclosure decisions and signs off. Nothing files itself.
Where this breaks — and how to measure it
The genuine disadvantages of AI in this workflow are specific, not philosophical:
- Transcription confidence is uneven. Handwritten fields, non-Latin scripts, low-resolution phone photos and stamped entries are where extraction quality drops. Require a confidence flag and human verification on document numbers and dates, always.
- Form editions drift. A field map built against one edition silently misfires on the next. Whoever owns the automation must own edition monitoring.
- Judgment calls masquerade as data entry. Whether a period of employment counts, how to characterize a relationship, what to disclose — these look like fields but are legal decisions.
- Confidentiality obligations don’t relax for convenience. The ABA’s Formal Opinion 512 on generative AI tools (2024) addresses competence, confidentiality and supervision duties when lawyers use these tools; your state bar may have its own guidance. Read both before you pipe client documents into anything. If client documents will leave your controlled environment, raise the specific configuration with your malpractice carrier and call your state bar’s ethics hotline before go-live, not after.
Don’t rely on vibes to decide whether extraction is working. Pick a sample size and hold to it: pull ten completed packages a month (or every package, if you file fewer than ten), and have the reviewer count field-level corrections made against the source document — not “did it feel accurate,” but a tally of fields changed, split into critical fields (names, dates, document and receipt numbers) and non-critical ones. Set the threshold before you start. A reasonable starting rule: if any critical field requires correction in more than one sampled package in a given month, that document type goes back to manual entry until you’ve fixed the extraction and re-run the sample clean.
Modeling the payback without making up numbers
Don’t take anyone’s published savings figure, including a vendor’s. Build the model yourself from three terms:
- Time recovered = packages per month × minutes saved per package
- Cost side = hours recovered × your loaded staff cost per hour
- Revenue side = extra matters handled × average fee × realization rate
A worked example with clearly assumed inputs: assume you file 40 packages a month and assume the agent saves 25 minutes of paralegal data entry per package. That’s roughly 16.7 hours a month recovered. Multiply by whatever your loaded paralegal cost actually is to get the cost-side figure, then decide honestly whether those 16.7 hours convert into additional consultations. Every one of those inputs is an assumption you should replace with your own measured numbers before spending anything.
The revenue term only counts if the recovered hours go somewhere useful — more consultations, faster turnaround that wins referrals, or reduced overtime. If the time just evaporates, you bought a convenience, not an investment. The same trap is covered in more depth in the build-vs-hire math for AI agents, paralegals and outsourcing.
A practical decision rule
If your firm files across many case types at modest volume and your main pain is deadlines and form maintenance, buy the immigration platform and use its built-in AI as it matures. If you file a lot of the same three case types and your bottleneck is turning client document chaos into clean data, a custom extraction agent in front of your existing platform is likely the higher-leverage build — and it doesn’t require ripping anything out.
There is also a legitimate third answer: neither. Firms handling a low monthly package volume, or working in only one or two case types, are usually better served by tightening the paper checklist and rewriting the client document-request email so uploads arrive labelled and complete — that fixes more of the problem than any AI layer, at zero recurring cost. If you’re not sure, run one case type manually for a month with a written checklist first. A workflow you can’t describe precisely is a workflow no agent can execute reliably.
And if your intake is the real leak — leads that never become matters — fix that before form prep; see the intake automation playbook. Automating the back end of a pipeline that isn’t full is the most common sequencing mistake in firm automation.
Where is your firm losing billable hours?
Get a free automation audit: we map your intake-to-invoice workflow and show you exactly what's worth automating — before you spend a dollar.
Get a free automation auditRelated guides
AI Agent vs Paralegal vs Outsourcing: Small Firm Math
Law firm AI automation, a paralegal hire, or outsourcing? An honest, vendor-neutral comparison of how small firms should add capacity — with the math to decide.
Read guide →
AI Dictation for Lawyers: Dragon vs Word vs Custom Agent
Compare Dragon legal dictation, built-in Word/Microsoft 365 dictation, and a custom AI agent that turns dictation into filed drafts, time entries, and tasks.
Read guide →
Medical Records Retrieval: Services vs a Custom AI Agent
Compare outsourced medical records retrieval services, paralegal-run processes, and a custom AI agent — with an honest look at where agentic law firm automation fits.
Read guide →